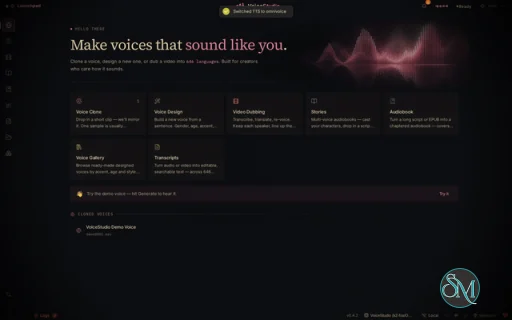
VoiceStudio is a useful text to speech application for users who want to turn written text into natural sounding speech. It is designed for people who need voice generation without having to record every sentence manually, making it suitable for content creation, accessibility, presentations, narration, and other voice based projects.
One of the main advantages of VoiceStudio is its focus on making voice generation accessible. Instead of requiring professional recording equipment, users can generate spoken audio from text and adjust the result according to their needs. This can save considerable time when producing longer narration or repeated voice content.
VoiceStudio can also be useful for experimenting with different voices and speaking styles. Depending on the supported engine and configuration, users may have control over characteristics such as speech rate, pitch, and other voice parameters. This gives more flexibility than a basic text to speech reader.
Another appealing aspect is its potential for voice cloning and AI based voice generation. These capabilities can be useful for creators who want a consistent voice across videos, tutorials, podcasts, or other digital content. However, voice cloning should always be used responsibly and with appropriate permission from the person whose voice is being replicated.
The application can also fit well into accessibility workflows. Converting text into speech can make written information easier to consume for users who prefer listening rather than reading. It can also be useful for proofreading, allowing writers to hear how their text sounds when spoken aloud.
VoiceStudio is not necessarily aimed at replacing professional voice actors in every situation. AI generated speech can still have limitations with pronunciation, emotion, pacing, and context. Results can vary considerably depending on the voice engine and the quality of the input text.
The learning curve will also depend on how many features you want to use. Basic text to speech is relatively straightforward, while more advanced voice customization and cloning features may require additional experimentation.
Overall, VoiceStudio is an interesting option for users who want convenient access to modern speech generation tools. It combines the practicality of text to speech with more advanced voice capabilities, making it useful for both casual users and content creators.
Download VoiceStudio v0.5.6 - Software Mirrors |
|---|
VoiceStudio v0.5.6 for Windows |
VoiceStudio v0.5.6 for macOSVoiceStudio-Electron-0.5.6-mac-x64.zip | 262.5 MB VoiceStudio-Electron-0.5.6-mac-x64.dmg | 262.28 MB |
VoiceStudio v0.5.6 for Linux |
VoiceStudio v0.5.6 Source Code |
VoiceStudio v0.5.6 Release Notes:VoiceStudio now talks to your other tools. Answer Twilio phone calls in a saved voice, and connect Claude Code, Cursor, Codex CLI and the OpenAI Agents SDK to VoiceStudio with copyable setup that works, including in Docker, where MCP previously returned HTTP 405. Integration cards now say plainly which ones work with VoiceStudio and which are external links. This release also lets you replace a saved clone's reference sample, clones long reference clips on OmniVoice, finishes long audiobook chapters on 8 GB GPUs, and keeps rendered chapters through a power-off or data-folder move. Download
/mcp keep working; new exports use /mcp/. OpenAI-compatible /v1 clients now get OpenAI-format errors with HTTP 400 instead of 422, and response_format="mp3" returns real MP3.
Moving from Tauri: Close the app, back up its data directory, install Electron, and verify your voices and projects before removing Tauri. Follow the migration guide. Tauri v0.5.3 remains the final Tauri release; its updater cannot install Electron.
Installer trust: Electron installers are unsigned or ad-hoc signed and are not Apple-notarized. Windows/macOS may show trust warnings. macOS automatic updates are unverified; use manual installer updates. See the installation guide.
Highlights
Changed
Added
Fixed
Docs
Contributors
Bug reporters
|
Install
Download packages from the latest release. First launch creates a managed Python environment and downloads the default model. Later launches reuse both.
Note
On macOS, first launch needs a one-time right-click → Open approval. Intel Macs cannot run the local Python backend; use a remote backend instead.
First voice
Launch VoiceStudio and open Voice Cloning.
Add a clean voice sample. Three seconds works; 5–15 seconds usually gives a better prompt.
Enter text, choose a language, then select Generate.
Run from source
Install the development prerequisites, then:
git clone https://github.com/debpalash/VoiceStudio.git
cd VoiceStudio
bun install
bun run desktop
Use bun run dev for the browser UI. See Contributing for services, tests, and platform packages.
If setup fails
Run Settings → About → Run self-check or
uv run python backend/main.py --diagnose --deep.Check install troubleshooting.
Save a scrubbed diagnostic bundle from the app when opening an issue.
For slow generation, compare measured benchmarks and performance settings.
Pros
Convenient text to speech generation
Useful for narration and content creation
Can reduce the need for manual voice recording
Voice customization options
Useful for accessibility
Potentially useful for consistent voice production
Cons
Voice quality can vary depending on the selected engine
AI voices may still sound less natural in some situations
Advanced features can require experimentation
Voice cloning requires responsible use and proper authorization
Final Verdict
VoiceStudio is a capable voice generation tool for anyone who needs to convert text into speech quickly and consistently. Its usefulness extends from simple accessibility applications to more creative projects such as video narration and digital content.
It is not a complete replacement for professional voice recording, but its convenience makes it a practical addition to an AI focused content creation workflow.
Developer:
VoiceStudio.sh
Operating System:
Windows / macOS / Linux
Date Added:
2026-09-23T14:03:39.768Z
Categories:
Post a Comment/Report Broken Link: