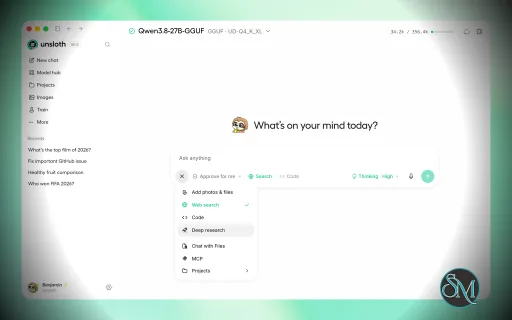
Unsloth is an open-source AI platform for running and training open models locally. It combines Unsloth Studio, a graphical interface for running and training models, with Unsloth Core, a code-based library for fine-tuning and machine learning workflows. It supports language, vision, audio, embedding, and diffusion models across Windows, Linux, WSL, and macOS.
The project is particularly focused on making model fine-tuning more efficient by reducing memory usage and improving training performance. It can also run local models and connect them to coding agents and other tools.
Features
Unsloth provides a graphical environment for downloading, running, and training open models. Users can search for models, run them locally, fine-tune them, and export the resulting models to formats such as GGUF and safetensors.
Key features include:
Local LLM inference
LLM fine-tuning
Vision and multimodal models
Audio models
Embedding models
Diffusion models
GGUF support
MLX support
LoRA and other fine-tuning workflows
Model export
RAG
Web search
Tool calling
Code execution
MCP support
Multi-GPU support
Claude Code integration
OpenAI Codex integration
OpenCode integration
Docker support
Self-hosted web interface
Python API and notebooks
Unsloth Start can connect local models to supported AI coding agents, allowing tools such as Claude Code and Codex to use models running through Unsloth.
The platform also supports several hardware backends. The project lists NVIDIA, AMD, Intel, CPU, and Vulkan support, although capabilities differ depending on the hardware and workload.
Download Unsloth v0.1.900-beta - Software Mirrors |
|---|
Unsloth v0.1.900-beta for WindowsUnsloth-Desktop-Windows.exe | 21.13 MB Unsloth-Desktop-Windows-ARM64.exe | 20.63 MB |
Unsloth v0.1.900-beta for macOSUnsloth-Desktop-MacOS.dmg | 22.61 MB |
Unsloth v0.1.900-beta for LinuxUnsloth-Desktop-Ubuntu.deb | 24.3 MB Unsloth-Desktop-Ubuntu-ARM64.deb | 24.56 MB Unsloth-Desktop-Linux.AppImage | 171.12 MB |
Others Download related to Unsloth v0.1.900-betaUnsloth-Desktop-ARM64.app.tar.gz | 22.4 MB |
Unsloth v0.1.900-beta Source Code
Unsloth v0.1.900-beta Source code (zip)
Unsloth v0.1.900-beta Source code (tar.gz)
|
Unsloth v0.1.900-beta Release Notes: We're adding support for decision models, a unified Library for docs and media, document viewer, many Apple Silicon improvements, creation of Skills, and ~4.5× faster image and video generation.
- Run and serve Decision Models like Laya (open-source Jev) locally
- Skills Editor to create, edit, and delete Skills directly in Desktop
- ModelScope model downloading is now here for users who can't use HF
- Library + Document Viewer for PDF, Word, Excel, PowerPoint, and chats.
- Apple Silicon Improvements including batched serving, structured outputs, and TurboQuant KV cache.
- Configure how much of a model each GPU receives.
- Faster Image + Video Generation with ~4.5x faster LTX-2.3 clips and 1.7–6.3x faster VAE decoding.
- New food-inspired Themes. Check them out!
Library + Viewer
- View PDF, Word, Excel, and PowerPoint files directly in Unsloth, with links back to their source.
- Manage chats, images, videos, everything in our new Library tab.
- Improved attachment cards and support for reading more file formats.
- Create your own sidebar sections and drag sections to reorder them.
Laya + decision models
Run Laya decision models locally to answer yes/no, multiple-choice, and scoring questions with probabilities.- Enable the Decision API from Settings > API, with model selection and CPU or GPU controls.
- Supports the TypeSafe SDK through a Jev-compatible
/v1/systemone endpoint. - Runs natively on MLX for Apple Silicon when GPU is selected. [Details](https://github.com/unslothai/unsloth/pull/11603)
Faster image + video generation
- LTX-2.3 clips are ~4.5x faster with distilled sampling, compile fixes, and hosted FP8 weights.
- Image and video VAE optimizations deliver 1.7–6.3x faster decoding, with total generation speedups depending on the workflow.
- MiniMax-H3's first render is up to a minute faster, with 25–29 GiB lower peak memory on A100, B200, and RTX PRO 6000.
Apple Silicon + MLX
- Batched serving allows multiple replies to decode at once.
- Added grammar-constrained structured outputs through
response_format. - Added TurboQuant KV cache and KV cache quantization for sliding-window models such as Gemma 4.
- Improved memory estimates and automatic context sizing based on available memory.
Skills + chat improvements
- Create, edit, and delete Skills from the Desktop Skills menu.
- Improved conversation recall across repeated auto compactions.
- Long-running tool calls continue even when they produce no output, with better protection against excessive output consuming memory.
- Auto-scroll or manual scroll your conversations
- Use ModelScope instead of Hugging Face for model downloads
Training + inference
- Faster block-FP8 LoRA training and support for LoRA on compressed-tensors W8A8 checkpoints.
- Load Voxtral and Qwen2-Audio through
FastModel. - Export saved checkpoints from crashed or cancelled training runs.
- Important compatibility fixes for Gemma, newer TRL trainers, and FP8 on RTX 5090 and RTX PRO 6000.
What's Changed- Wait for the model load before reading the unsloth run banner by @danielhanchen in #11679
- Bump install.sh / install.ps1 pin to unsloth>=2026.9.11 by @danielhanchen in #11689
- Revert "Studio: steady the Images and Video loading spinners, and tidy the progress card" by @shimmyshimmer in #11691
- Follow #11635's Diffusers prefetch and #11660's responsive classes in the tests by @danielhanchen in #11680
- Give the ROCm bf16 chain test every name _gpu_init imports from device_type by @danielhanchen in #11688
- Read the sidebar pin's width only where matchMedia exists, and expect the update card's scaled width by @danielhanchen in #11700
- Keep a test's fake pid identity out of the cached owner identity by @danielhanchen in #11708
- Expect the unsloth Z-Image-Turbo mirror in the image download queue drive by @danielhanchen in #11711
- Classify uv's new --output-format as a value flag in the pip shim by @danielhanchen in #11715
- Studio: do not roll back a model switch whose load got no answer by @danielhanchen in #11729
- studio: add responses api selection for custom providers by @mahiatlinux in #11354
- Count the stripper's whole-buffer work instead of timing it by @danielhanchen in #11735
- Studio: keep tracking a new chat's upload when its id commits late by @danielhanchen in #11738
- studiobench: compare a code fence one arm scrolled past on its text by @danielhanchen in #11741
- Anchor the GRPO MoE aux-loss fail-fast on the assignment, not its expression by @danielhanchen in #11747
- Chat UI driver: wait for the Recents thread to load, and let the check fail by @danielhanchen in #11749
- Clean-machine trace leg: let git fetch the pinned git+ requirements, nothing else by @danielhanchen in #11751
- Studio: add Search Hub to the Images, Video and Audio model pickers by @shimmyshimmer in #11756
- Studio: keep the model name and quant whole in the Images and Video header by @shimmyshimmer in #11757
- Studio: drag to reorder, add to project and quick download for the image and video galleries by @shimmyshimmer in #11758
- Studio: make the Images, Video and Audio settings rail resizable by @shimmyshimmer in #11760
- Studio installer: do not run Apple's git shim to ask whether git works by @danielhanchen in #11759
- Data settings check: pin the legacy store outcome in the failed-delete check by @danielhanchen in #11763
- Update idempotency: count whisper.cpp only when the install has one by @danielhanchen in #11762
- Account matrix: cover the gallery move and add-to-project routes by @danielhanchen in #11767
- Studio: stop clipping the model description's descenders; follow the resizable rail in the layout contracts by @danielhanchen in #11769
- Studio: follow-ups for the media gallery, hub link and rail divider by @shimmyshimmer in #11765
- studiobench: do not fail UI parity on repetitions that swap two renderings by @danielhanchen in #11772
- MCP HTTP integration test: let the server bind its own port by @danielhanchen in #11777
- Export full fine-tunes in 16-bit from the CLI by default by @NilayYadav in #11716
- Studio: end Alpaca training samples with the end token by @NilayYadav in #11719
- Studio: keep Qwen-Image-2.1 int8 / fp8 compiling on torch 2.12 (CantSplit) by @danielhanchen in #11677
- Studio: let an explicit FBCache request engage on Qwen-Image-2.1 and other prefix-KV models by @danielhanchen in #11713
- Studio: make the HunyuanImage-2.1 denoiser step capturable as a CUDA graph by @danielhanchen in #11753
- Studio: pin, reorder and add to project for Audio history by @shimmyshimmer in #11774
- Studio: Show token usage and cache stats on connected provider chats by @NilayYadav in #11717
- fix(studio): support preserve thinking for llama.cpp connections by @Imagineer99 in #11706
- Studio: stop the max speed tier recompiling on every new prompt length by @danielhanchen in #11731
- Layout contract: tie the Train rail clamp to its scroller's padding by @danielhanchen in #11773
- Studio: fix broken Chinese, Japanese and emoji text in gpt-oss replies by @NilayYadav in #11720
- Studio: Keep Codex reasoning between tool calls on /v1/responses by @NilayYadav in #11726
- Studio: Make
unsloth start --reasoning on/off take effect by @NilayYadav in #11718 - Studio: example prompt per image workflow, remember the last prompt by @shimmyshimmer in #11775
- Studio: dock the floating Live monitor beside Run settings by @wasimysaid in #11699
- Account matrix: cover the audio gallery move and add-to-project routes by @danielhanchen in #11789
- Studio: show the Custom size fields under Output size in unified Edit by @oobabooga in #11690
- Fix false ONNX rejection for models with native weights by @wasimysaid in #11695
- Fix GGUF vision capability selection by @wasimysaid in #11696
- Baseline the two huggingface_hub 1.33.0 / 2.0.0 findings after review by @danielhanchen in #11811
- Replace an in-flight chat model load with the latest pick by @wasimysaid in #11697
- Prebuilt installers: retry a download the server drops by @danielhanchen in #11816
- Load-replacement contract: read the rollback guard, not its one-line spelling by @danielhanchen in #11817
- Unsloth Studio (AMD/ROCm): don't turn on cudnn.benchmark for image and video generation by @LeoBorcherding in #11732
- Padding-free gate tests: state that UNSLOTH_RETURN_LOGITS is unset by @danielhanchen in #11863
- Eval step: restore UNSLOTH_RETURN_LOGITS even when evaluation raises by @danielhanchen in #11865
- Studio update launcher tests: give every test a private STUDIO_HOME by @danielhanchen in #11869
- Studio: a sandbox read waits out a legacy move's staging window by @danielhanchen in #11876
- Agent guides CI: pass optional installer flags only while the installer takes them by @danielhanchen in #11878
- fix(studio): keep Stop generating visible while queuing by @Biotrioo in #9123
- Studio: give the Windows ROCm torchao stub a version transformers 5 can parse by @danielhanchen in #11640
- Give vLLM a valid top_k when fast_inference enables it in the GRPO trainer by @danielhanchen in #11675
- Studio: stop unsloth start announcing a switch when --model names the file already loaded by @oobabooga in #11873
- Studio: stop holding a passthrough response 5 s when a watcher swallows its cancel by @oobabooga in #11859
- Studio: say the installer script is missing instead of showing the PowerShell logo by @oobabooga in #11862
- Studio: stop rescanning every model folder on each request that names a model not on disk by @oobabooga in #11872
- studiobench: image_upload closes the menu it opened when it gives up by @danielhanchen in #11892
- Parallel-isolation guard: exempt the resolver's back-dated staleness precondition by @danielhanchen in #11894
- Studio: stop opening a saved chat from re-running a Max Tokens reply by @shimmyshimmer in #11875
- Studio: use the browser's timezone for today's date in chat by @NilayYadav in #11852
- SentenceTransformer: preserve masks for patched Gemma3 attention by @Etherll in #11866
- Studio: initialize new chats before attaching documents by @Imagineer99 in #11838
- Studio: stop inflating chat images by re-encoding every one to PNG by @oobabooga in #11889
- Studio: fix document search for embedding models other than the default by @NilayYadav in #11853
- Studio: train audio datasets on the columns the dataset check found by @NilayYadav in #11850
- Studio: follow the JSON format a client asks for on /v1/messages by @NilayYadav in #11854
- Studio: let a temporary chat be saved to history by @shimmyshimmer in #11901
- Studio Hub: show a running download as Downloading, not as a paused partial by @danielhanchen in #11797
- Accept the transformers 5.0 ignore_keys argument in validate_rope by @danielhanchen in #11560
- Studio: verify the Diffusers main zip against a pinned SHA-256 by @danielhanchen in #11908
- Studio: restyle the save temporary chat popup as a standard dialog by @shimmyshimmer in #11914
- Fix text_only 4-bit load and generate for Gemma-4 and other VLM text configs by @danielhanchen in #11684
- Studio: add File and View menu items to the macOS desktop app by @shimmyshimmer in #11902
- Studio: keep the model's own chat template when the Unsloth one can't render the rows by @oobabooga in #11487
- Split the flash-attn prebuilt wheel build across parallel ccache jobs by @oobabooga in #11812
- Studio: find older chats by title in chat search by @NilayYadav in #11296
- Studio: fix login failures during slow startup by @NilayYadav in #11289
- Studio: build Qwen-Image-2.1's token layout once per render instead of every step by @danielhanchen in #11887
- Load a VLM through its native image-text class when the repo's auto_map class is untrusted by @danielhanchen in #11613
- Unsloth Studio (AMD): floor torch at 2.11 on the gfx103X-all and gfx110X-all families too by @LeoBorcherding in #11834
- Studio: read DOCX content controls, tracked insertions and text boxes by @L4XB in #11803
- Studio: start settings labels with the setting, not "Show" by @shimmyshimmer in #11924
- Studio: align the model selector label and truncate long project names by @shimmyshimmer in #11917
- Studio: style the chat scrollbar like Run settings by @shimmyshimmer in #11925
- Unsloth Studio (AMD/ROCm): warn about, and refuse, a GPU the installed PyTorch has no kernels for by @LeoBorcherding in #11571
- Studio: video auto precision keeps a resident bf16 DiT by @danielhanchen in #11831
- Studio: show Theme first in Settings > Appearance by @shimmyshimmer in #11921
- Stop the Starling, Yi-chat and LFM2 templates leaking whitespace by @Abhishek-B-R in #11779
- Studio: clicking a gallery item keeps the typed prompt by @shimmyshimmer in #11930
- Studio: move Read aloud and Edit response into the More menu by @shimmyshimmer in #11920
- Studio: make the composer the same width as the chat column by @shimmyshimmer in #11926
- UI scale contract: count the save-temporary-chat button among the chat header's 30px controls by @danielhanchen in #11932
- studio: allow local imatrix files for gguf export by @mahiatlinux in #11350
- Studio: guard export operations when the Hub is unreachable by @Imagineer99 in #11466
- Studio: keep a Codex chat working after a tool returns an image on a text-only model by @NilayYadav in #11476
- Studio: show example prompts as placeholder hints by @shimmyshimmer in #11931
- Studio: keep a chat's attached files when you fork it by @NilayYadav in #11295
- Studio: add a multiline send shortcut and spell out what each one does by @shimmyshimmer in #11927
- Studio: stream durable chat runs at display frame rate by @shimmyshimmer in #11900
- Embed server tests: intercept only the server's own Popen by @danielhanchen in #11934
- Studio: build the ConvRot rotation from its definition by @danielhanchen in #11807
- Studio: keep all text when adding Word files to a knowledge base by @NilayYadav in #11725
- Studio: show when a response was written, in its More menu by @shimmyshimmer in #11928
- Studio: load the hosted INT8 pre-quant checkpoints on torchao 0.18 and later by @danielhanchen in #11884
- Studio: show context checkpoints apart from the KV cache in the memory estimate by @oobabooga in #11581
- Studio: drag to reorder pinned models in the model picker by @shimmyshimmer in #11941
- Cast fp16 leftovers to the requested dtype after a text_only pre-quantized load by @danielhanchen in #11692
- Studio: translate the inline Read aloud and Edit response settings by @shimmyshimmer in #11933
- Accept block_sequence_ids in chunked causal masks on transformers 5.17 by @danielhanchen in #11693
- Studio: convert decoded video frames to uint8 on the GPU before the mp4 encode by @danielhanchen in #11879
- Studio: fix pinned rows in the model picker by @shimmyshimmer in #11943
- Studio: stop rewriting the compile-cache bundle on every warm start, and bound its disk use by @danielhanchen in #11874
- Studio: list the Images workflows in the phone sidebar again by @oobabooga in #11936
- Studio: reuse unchanged files from an older snapshot instead of re-downloading them by @danielhanchen in #11796
- Studio: draw one drop line per gap when dragging sidebar rows by @shimmyshimmer in #11942
- Studio: show the full URL while a web fetch waits for approval by @wasimysaid in #11694
- Rebuild byte-level tokenizers that transformers v5 loads as LlamaTokenizer by @danielhanchen in #11686
- Plan a device map for text_only loads of vision-language models by @danielhanchen in #11584
- Installer: stop picking cu126 when a slow NVIDIA driver times out CUDA detection by @danielhanchen in #11916
- Studio: skip xFormers when its torch requirement is unmet by @oobabooga in #11847
- Studio: add HTTP recording fallback to Dictate by @Etherll in #11075
- Studio: propagate the Ollama CUDA runtime to llama-server (replacement for #7563) by @wasimysaid in #11666
- Prevent setup-size flash during desktop startup by @wasimysaid in #11910
- Studio: return freed host memory to the OS after diffusion and video unload by @danielhanchen in #11795
- Walk every sub-config when deciding whether a config carries remote code by @danielhanchen in #11555
- Studio: fix vision training with evaluation on when there is no eval split by @NilayYadav in #11851
- Studio: stop a compiled Qwen-Image-2.1 render holding 2 GiB of prefix K/V it does not need by @danielhanchen in #11882
- Dequantize FP8 weights left raw by text_only and offloaded loads by @danielhanchen in #11841
- Studio: video status reports CUDA graphs off when they never engage by @danielhanchen in #11886
- fix(studio): show compaction notices for tool-loop checkpoints by @Imagineer99 in #11702
- Pin the ARM64 Arrow overlay to a commit before its wheels are signed by @danielhanchen in #11911
- Load 4.x remote code and config-only remote code on transformers 5 (Trinity-Large, MiniMax-M3) by @danielhanchen in #11658
- Studio: serve the Jev API locally with Laya by @NilayYadav in #11603
- Studio: opt-in NVENC for the video mp4 export by @danielhanchen in #11881
- Studio: compile the diffusion denoiser on fp16 GPUs when a speed tier is picked (T4 and other pre-Ampere cards) by @danielhanchen in #11899
- Studio: whole-model offload points weights back at their host tensors instead of copying them by @danielhanchen in #11764
- Studio: pin the kept offload weights on first onload when host RAM allows by @danielhanchen in #11766
- fix(studio): count rendered GGUF prompts before shared-KV admission by @Imagineer99 in #10794
- Point -bf16 4-bit requests at quantization_config, and warn when a bitsandbytes load quantized nothing by @danielhanchen in #11586
- Studio: HunyuanVideo-1.5 padded-text trim on the max speed tier by @danielhanchen in #11824
- Studio: release VRAM when an image model is unloaded mid-render by @danielhanchen in #11790
- Studio: faster MiniMax-H3 video VAE encode and decode by @danielhanchen in #11801
- fix(grpo): use the evaluated model's output head for log-probs by @taking-lying-flat in #11877
- Studio: auto step cache (FBCache) only on the max speed tier by @danielhanchen in #11791
- Studio: cache text-encoder outputs so repeat prompts skip the encoder by @danielhanchen in #11844
- fix(studio): classify MLX requests from the applied chat template override by @Lyxot in #11903
- Unsloth Studio (AMD): allow INT8 / FP8 image and video precision without torchao by @danielhanchen in #11631
- Studio: count the hosted text encoder and keep the GGUF denoiser resident when only the encoder does not fit by @danielhanchen in #11802
- Studio: run an explicit int8 under offload on NVIDIA as torchao-free W8A8 by @danielhanchen in #11712
- Studio: apply remembered settings for MLX and safetensors models to API loads by @Lyxot in #11904
- Studio: keep bf16 for auto precision on image families that cannot compile by @danielhanchen in #11819
- Studio: tile the VAE instead of refusing oversized upscales, and in-app remedies for image refusals by @danielhanchen in #11798
- Load and train remote-code multimodal wrappers: Phi-4-reasoning-vision in 4-bit and Nemotron-3-Nano-Omni by @danielhanchen in #11526
- Finish a 16bit load of a static per-tensor fp8 checkpoint (Mistral-Small-4) by @danielhanchen in #11531
- Studio: static step skip for image models that keeps CUDA graphs by @danielhanchen in #11737
- Studio: static step skip for video generation by @danielhanchen in #11748
- Studio: Qwen-Image-2.1 RoPE in real arithmetic inside the compiled blocks by @danielhanchen in #11888
- Studio: Library page for files, media and fine-tunes by @shimmyshimmer in #11770
- Resolve remote-code model classes, reach per-expert submodules with LoRA, run the root dispatch hook on the embedding's device (Nemotron-Labs-Teacher) by @danielhanchen in #11543
- Studio: Library settings, storage and sortable list columns by @shimmyshimmer in #11771
- Studio: open Images and Video previews in the Library viewer by @shimmyshimmer in #11776
- Format the two files #11526 left off the formatter's fixed point by @danielhanchen in #11955
- Load and fine-tune LongCat-Flash-Lite-Sparse on transformers' longcat_flash by @danielhanchen in #11620
- Hand a composition with no forward of its own to its thinker (Qwen3-Omni) by @danielhanchen in #11523
- fix(studio): retain GGUF quants across cache-folder switches by @wasimysaid in #11938
- Keep the training state intact across a standalone evaluate() / predict() by @danielhanchen in #11860
- fix(studio): recover from a dead Metal GPU queue instead of failing every later request by @Lyxot in #11383
- Pin the compiled mask wrapper only when it is compiled by @danielhanchen in #11957
- Load NVIDIA ModelOpt FP8 checkpoints through the transformers fp8 quantizer by @danielhanchen in #11592
- Studio: run Qwen-Image-2.1 int8/fp8 on 24 GB cards with the transformer resident and the text encoder streamed by @danielhanchen in #11883
- Divide by gradient accumulation for forwards that take kwargs but return a mean loss by @danielhanchen in #11898
- Load 4.x-era configs that transformers 5 strict validation rejects (Llama 4 attn_temperature_tuning) by @danielhanchen in #11836
- Studio: minimal OS sandbox for Python and Terminal tools on Linux and macOS by @oobabooga in #11209
- Studio: add Windows MXC Preview sandboxing by @Etherll in #11390
- Studio: whole-model NVFP4 for the video families with hosted pre-quantized denoisers by @danielhanchen in #10729
- Studio: per-layer NVFP4 image policies, flashinfer FP4 backend and a gated auto row by @danielhanchen in #10730
- Studio: NVFP4 flashinfer backend kernel items (device guard, persistent barrier, bias path, cached dispatch) by @danielhanchen in #10731
- Studio: keep inline HTML text in its line when parsing an upload by @L4XB in #11818
- Studio: read text, Markdown and HTML uploads in the encoding they were written in by @L4XB in #11896
- Fix PEFT base export targets silently exporting the base model by @tweekli in #11781
- Studio: install flashinfer on demand for NVFP4 without moving torch by @danielhanchen in #11730
- Studio: steady pinned model drop line and pill-shaped project drop highlight by @shimmyshimmer in #11986
- Studio: compile the VAE decode for DiT families, from the NVFP4 time budget pass by @danielhanchen in #10889
- Studio: Library grid Sort menu, tidier toolbar menus and card icons by @shimmyshimmer in #11978
- Studio: cap context checkpoints by host RAM for sliding-window and SSM models by @Lyxot in #11918
- Studio: sort projects in the sidebar and show pinned chats once by @shimmyshimmer in #11988
- Studio tests: read UI labels from the en catalog, and follow the response-details action into MessageMenuTime by @danielhanchen in #11949
- Studio: open model row tooltips from the name only by @shimmyshimmer in #11985
- Studio: pin fine-tuned models in the model picker by @shimmyshimmer in #11984
- CI: only cancel superseded pull request runs, never dispatches or schedules by @danielhanchen in #11977
- CI: fix path filters that miss dependencies, and narrow three that are too broad by @danielhanchen in #11989
- Studio Playwright helpers: named per-step budgets, fail-fast step report, condition waits by @danielhanchen in #11979
- Studio Playwright chat_ui: condition waits, per-step budgets, 25 s less in the theme step by @danielhanchen in #11983
- Studio Playwright: condition waits and per-step budgets in extra_ui and update_banner_layout by @danielhanchen in #11990
- Studio Playwright: condition waits and per-step budgets in model_config and memory_estimate by @danielhanchen in #11987
- Studio Playwright: condition waits and per-step budgets in loaded_models_indicator and ui_font_scale by @danielhanchen in #11992
- Studio Playwright: condition waits and step budgets in thread_scoped_settings, mcp_arguments, chat_width by @danielhanchen in #11991
- Export: add save_pretrained_openvino and push_to_hub_openvino support by @goodmai in #11907
- Studio: line sidebar section headers up with row content by @shimmyshimmer in #11996
- CLI: keep a reply's trailing '<' or '#11893
- Studio: drop Move up / Move down from sidebar row menus by @danielhanchen in #12000
- Studio: Help menu items and a Go menu for desktop Help search by @shimmyshimmer in #12002
- Studio: size Library gallery items without resolving each file by @danielhanchen in #12003
- Fix left-padded Online DPO scoring during training by @taking-lying-flat in #11885
- feat(studio): ModelScope as a model source and a custom Hugging Face endpoint by @Lyxot in #11761
- Keep the Kaggle GPU harness tests independent of the caller's CUDA_VISIBLE_DEVICES by @danielhanchen in #12010
- OpenVINO export: trust remote code only for a remote-code model, and decode the bounds probe as UTF-8 by @danielhanchen in #12012
- Skip test_wait_for_settled when playwright.sync_api is only a stub by @danielhanchen in #12013
- feat(install): fall back to CERNET and npmmirror when package hosts are blocked or slow by @Lyxot in #11786
- Skip Unsloth's generated compile cache in the exec-literal lint by @danielhanchen in #12014
- tests: make the ROCm install suite pass on Windows, macOS and arm64 runners by @danielhanchen in #12005
- Studio setup: read the amd-smi index-space line without head -n 1 by @danielhanchen in #12004
- Add longcat_flash_lsa to the fused-MoE conversion snapshot by @danielhanchen in #12018
- Record only the test thread's sleeps as Deep Research retry backoff by @danielhanchen in #12019
- Studio CLI: stop
unsloth run re-exec'ing itself forever when the Studio venv is a symlink by @danielhanchen in #11788 - Studio: do not reapply ROCR_VISIBLE_DEVICES when picking the AMD card in setup.sh and the llama.cpp prebuilt probe by @danielhanchen in #11965
- Studio: run image and video denoises on one render thread so cuDNN caches are reused by @danielhanchen in #11843
- Studio: return an error when embeddings dimensions can't be honored by @NilayYadav in #11968
- Studio: keep a 0 label and blank a NaN cell when mapping columns to chat roles by @breken-ai in #11895
- Studio: support web_search_20260209 on /v1/messages by @NilayYadav in #11963
- Studio: keep a working GPU when one probe fails, and name the card behind no_gpu by @danielhanchen in #11944
- Studio: download only one copy of a GGUF quant by @NilayYadav in #11966
- Give the real-host NVIDIA probe test a budget that a busy driver can meet by @danielhanchen in #12026
- Unsloth Studio installer (AMD/Linux): send RDNA 4 cards (RX 9000, R9700) to AMD's gfx120X wheels by @danielhanchen in #11935
- Studio: keep a CSV seed's values as written when dropping its index column by @L4XB in #11945
- Studio media viewer: Zoom to fit at the bottom of the scale menu by @shimmyshimmer in #12028
- Studio: shadow the dark mode composer so it stands off the chat by @shimmyshimmer in #12023
- Studio: name the Git Bash MXC incompatibility and stop re-probing it by @danielhanchen in #12021
- Keep more VRAM headroom on Windows CUDA, and say when a hand-set context does not fit by @danielhanchen in #11368
- Unsloth Studio (AMD): keep export off a GPU PyTorch has no kernels for, like the iGPU by @oobabooga in #11946
- Read the hot-path I/O cost at its steady minimum across repeats by @danielhanchen in #12029
- Unsloth Studio: a companion fetch with no denoiser no longer blocks deleting its base by @LeoBorcherding in #11828
- Studio: stop Python tool network calls from skipping the host allowlist by @oobabooga in #11172
- Studio: center collapsed sidebar icons and tighten the rail by @shimmyshimmer in #12031
- Unsloth Studio: list a GGUF with no header metadata under On Device on the Images page by @LeoBorcherding in #11830
- Keep the conversion backfill's donor stub off the transformers package by @danielhanchen in #12034
- Unsloth Desktop: show Stopping… after Stop so a pending cancel doesn't look ignored by @LeoBorcherding in #11976
- Studio: stop edit_file writing a compacted-argument placeholder into files by @oobabooga in #11950
- Studio: decode Wan video in fp16 with channels_last_3d convs by @danielhanchen in #11999
- Unsloth Studio: refuse picking a hosted FP8/INT8 checkpoint repo as a pipeline before it downloads by @LeoBorcherding in #11829
- Studio: stop the second prompt length recompiling Qwen-Image on the max tier and with int8 by @danielhanchen in #11842
- Studio: size the image memory plan at the dtype the pipeline loads in (SDXL resident on 24 GB) by @danielhanchen in #11922
- Studio: stop MiniMax-H3 recompiling on the second caption and the first i2v by @danielhanchen in #11880
- Unsloth Studio / Desktop: log what an image load and each generation actually resolved to by @LeoBorcherding in #11994
- Unsloth Studio: stop offering "Continue" on a base repo that only holds a GGUF's text encoder and VAE by @LeoBorcherding in #11644
- Apply SFTConfig.router_aux_loss_coef to MoE models that cache it at init by @danielhanchen in #12006
- Load only the language model for text_only on repo-code composites by @danielhanchen in #11861
- Put back the unsloth_zoo modules the device map opt-in tests stub by @danielhanchen in #12038
- Studio: pass tool_result is_error through to the model on /v1/messages by @NilayYadav in #11962
- SentenceTransformer: add opt-in FP32 merged-pair ranking loss by @Etherll in #11867
- Studio: opt-in Hadamard rotation for Qwen-Image-2.1's int8 transformer so it matches bf16 by @danielhanchen in #11835
- Grouped-linear LoRA for DeepSeek-V4, remote-code shims for Step-3.7, and a real message for Mistral-format checkpoints by @danielhanchen in #11528
- Studio: fall back to native when SageAttention does not run on this GPU by @danielhanchen in #11997
- Keep flash attention off sub-models that do not support it (LFM2.5-VL SigLIP2 tower) by @danielhanchen in #11959
- Studio: stop trading the denoiser's quantisation away to pay for offload by @danielhanchen in #11558
- Unsloth Studio: report the VAE decode on the image progress bar by @LeoBorcherding in #11740
- Translate the Library toolbar Sort menu in every locale by @danielhanchen in #12045
- Read the partial safetensors delete-menu guard by operator, not verbatim by @danielhanchen in #12042
- Resolve the macOS app menu's chords as a Mac in its test by @danielhanchen in #12046
- Advertise NVFP4 diffusion on the text encoder driver's mocked host by @danielhanchen in #12047
- Keep peft's is_torchao_available cache API through the stale-torchao patch by @danielhanchen in #12049
- Run the formatter fixed-point guard's batches side by side by @danielhanchen in #12050
- Let the macOS tab sampler ride out a navigation still in flight after login by @danielhanchen in #12053
- Studio: let Deep Research finish a turn handed off from a chat generation by @MohammadHijjawi97 in #11923
- Studio: custom sidebar sections, section menus and drag to reorder by @shimmyshimmer in #12016
- Studio: link folders when creating a project by @shimmyshimmer in #12057
- Studio: open the user menu Help submenu upward by @shimmyshimmer in #12032
- Skip chordless menu items in the native chord collision check by @danielhanchen in #12063
- Give the health wait's working-child tests room for the worker to start by @danielhanchen in #12065
- Count #12016's section header among the sidebar's scaled 30px rows by @danielhanchen in #12066
- Turn off Dr GRPO reward scaling under TRL's "group" default by @vineethsaivs in #11951
- Studio: keep the sidebar menu shadow in light mode by @shimmyshimmer in #12062
- Reset the permission step's storage at the start of the next document by @danielhanchen in #12073
- Let the Projects section stand in for its row in the macOS tab walk by @danielhanchen in #12074
- Load #11526's text-core refusal in the save_method routing harness by @danielhanchen in #12077
- Studio: read personalization only once a first sign-in has changed its password by @danielhanchen in #12071
- Studio: train a SQuAD answer's text, not the answers dict, when mapping columns to chat roles by @breken-ai in #12056
- Back off and retry the update banner navigation on ERR_NO_BUFFER_SPACE by @danielhanchen in #12081
- Keep TRL's own RL config defaults and clamp preference max_length by @danielhanchen in #12069
- Unsloth Studio (AMD/Windows): report an iGPU's used VRAM when a discrete card sits beside it by @LeoBorcherding in #11871
- CI: CodeQL advanced setup that analyses only the languages a PR touches by @danielhanchen in #11998
- Give the killed formatter grandchild as long to die as it had to start by @danielhanchen in #12086
- Studio: rework Appearance settings and add flavor color themes by @shimmyshimmer in #12030
- Studio: quieter settings headings and one section gap on every page by @shimmyshimmer in #12064
- Keep the padding-free column test off the datasets numpy formatter by @danielhanchen in #12082
- Studio: put Reapply next to Generate on the image and video pages by @LeoBorcherding in #11974
- Unsloth Studio / Desktop: keep the Images Cancel load pill off the model panel divider by @LeoBorcherding in #12079
- Studio: keep run duration on Mac when training with an eval set by @NilayYadav in #11967
- fix: handle strided cross entropy inputs by @MrCapricornLiu in #10713
- Stop unsloth chat and unsloth inference switching a loaded GGUF to a different quant by @NilayYadav in #11855
- Studio: tell Safari which account the Studio password belongs to by @NilayYadav in #11858
- Studio: find models in a Hugging Face cache folder added as a location by @NilayYadav in #11970
- Unsloth Studio installer (AMD/Windows): don't mistake ZLUDA for an NVIDIA GPU by @LeoBorcherding in #11736
- Studio: follow redirect pages when reading a web page by @NilayYadav in #11856
- Studio: don't stop long running tool calls that print nothing by @NilayYadav in #11969
- Studio: stop the dense-quant probes pinning a CUDA context on every card of a multi-GPU host by @LeoBorcherding in #11954
- Studio: reject echo, suffix and best_of on /v1/completions by @NilayYadav in #11964
- Fix the prebuilt wheel publish step and shorten its release notes by @danielhanchen in #12068
- Studio: stop generating when the client disconnects on a non-streaming request by @NilayYadav in #11961
- Studio: decode the SDXL VAE in fp16 on fp16 GPUs by @danielhanchen in #12036
- Studio: honor response_format on the MLX backend with grammar-constrained decoding by @Lyxot in #10180
- Studio: document viewer for PDF, Word, Excel and PowerPoint, with origin links in Library by @shimmyshimmer in #12001
- Studio: chat attachment cards, chips and the Library viewer by @shimmyshimmer in #12017
- Studio: keep an eagerly decoded image VAE contiguous on NVIDIA by @danielhanchen in #12035
- Studio: skip the cuDNN benchmark search for the MiniMax-H3 audio VAE on A100 / B200 / RTX PRO 6000 (first render up to a minute faster, 25-29 GiB lower peak) by @danielhanchen in #12040
- Studio: keep a chat's start date in the system prompt, note a new date on the latest user turn by @danielhanchen in #12096
- Keep Llama 3.2 Vision off flash attention (vision and cross attention have no is_causal) by @danielhanchen in #12033
- Load the repo AutoProcessor for AutoModel-only repo-code VLMs by @danielhanchen in #12037
- Unsloth Studio / Desktop: let the GPUs picker say how much of the model each card gets by @LeoBorcherding in #12015
- Studio: regionally compile Lumina-2 and HiDream-I1, and re-decide their auto precision by measurement by @danielhanchen in #12039
- Studio: refuse a hand-set Metal context only past the GPU wired limit by @Lyxot in #10804
- Studio: keep a pinned context as a request limit instead of refusing KV cache quantization by @Lyxot in #11084
- Studio: let full-scope keyless callers auto-switch models, and explain the refusal elsewhere by @Lyxot in #11180
- Upload all GGUF files in one commit so create_pr opens one pull request by @NilayYadav in #11857
- Studio: return an error when a model can't use the tools sent to it by @NilayYadav in #11960
- Read settings.py as utf-8 in the palette filter test by @danielhanchen in #12105
- Read settings.py as UTF-8 in the unknown-palette test by @danielhanchen in #12101
- Carry the resolved attention implementation to nested configs a remote config baked flash attention into (Nemotron 3 Nano Omni) by @danielhanchen in #12099
- Studio: share MLX VLM prompt-cache snapshot buffers and replay exact prompts by @Lyxot in #11659
- GRPO: default to TRL's dapo loss with beta 0, cap CISPO weights at 5.0 by @danielhanchen in #12088
- Patch the TRL trainers that moved to trl.experimental (ORPO, CPO, Online DPO, GKD, ...) by @danielhanchen in #12097
- Studio: quantize the KV cache of sliding-window MLX models such as Gemma 4 by @Lyxot in #11082
- Studio: cache and coalesce nvidia-smi reads in the backend by @danielhanchen in #11995
- Unsloth Studio installer (AMD/Linux): explain why a newer ROCm gets ROCm 7.2 PyTorch by @LeoBorcherding in #11651
- Treat a reaped grandchild as dead in the formatter timeout test by @danielhanchen in #12107
- Trim comments in the DeepSeek-V4 grouped LoRA, remote-code shims and Mistral-format loader code by @danielhanchen in #12089
- Keep ORPO / CPO rows within max_length on TRL 0.29+ by @danielhanchen in #12115
- Keep the Triton MoE grouped GEMM in compiled graphs and index weights past 2^31 elements by @danielhanchen in #12114
- Studio: read more chat attachment formats, and hand the rest to the python tool by @Lyxot in #11379
- Unsloth Desktop: Create, Edit, and Delete Skills from the Skills Menu by @LeoBorcherding in #11800
- Studio: show the Hub error for an unreadable GGUF repo instead of routing it to Transformers by @danielhanchen in #12117
- Count the MLX grammar engine slot in the Apple Silicon step totals by @danielhanchen in #12135
- Pass gradients through compressed-tensors activation quantization so W8A8 checkpoints train with LoRA by @danielhanchen in #11585
- Studio: keep the last full-attention layer unquantized in the MLX KV cache by @Lyxot in #11083
- Gate the Mllama CUDA forward test on has_real_cuda by @danielhanchen in #12143
- Batched serving on the MLX path: several replies decoding at once by @Lyxot in #10310
- Point dsh at Unsloth through a --patch overlay instead of settings.yaml by @danielhanchen in #12145
- fix(studio): mark /api reads no-store so an idle desktop app stops rewriting its disk cache by @alkinun in #12148
- Wait for every diffusion run a test started before undoing its runs dir by @danielhanchen in #12149
- Studio: move Managed accounts to the Accounts tab and drop Mark as unread from chat menus by @shimmyshimmer in #12120
- Studio: keep checkpoint compaction under --disable-tools by @danielhanchen in #12119
- Studio: only offer Agent Skills when Code is on by @danielhanchen in #12118
- Settle the permission step's reloads on the pill instead of networkidle by @danielhanchen in #12153
- Speed up block-FP8 LoRA training: run FP8 linears eagerly, 8 warps for 128-row GEMM tiles by @danielhanchen in #12027
- Fall back from FBGEMM for rowwise FP8 on GPUs it has no kernel for (RTX PRO 6000 / 5090) by @danielhanchen in #12098
- Studio: TurboQuant KV cache option for MLX inference by @Lyxot in #11170
- Fix rowwise FP8 scale axes in fused LoRA backward by @taking-lying-flat in #11799
- Unsloth Studio Installer: ask Python for a path identity before giving up on an exact one by @danielhanchen in #11104
- Ask Python for the process image table when the native helper is unavailable by @danielhanchen in #11115
- Refresh a rewritten shortcut's icon where the shell cannot define the type by @danielhanchen in #11116
- Recover CUDA compute capabilities without emitting a P/Invoke type by @danielhanchen in #11173
- Remove the reflection-emit apparatus and all four emitted types by @danielhanchen in #11193
- Add a Windows probe for code integrity blocks, and audit bundle signatures in CI by @danielhanchen in #10408
- Windows installers find an NVIDIA GPU on the PCI bus, and say which CUDA it can use by @danielhanchen in #11166
- Fix Gemma2 padding masks during batched cached decoding by @taking-lying-flat in #12008
- Gemma2: use flash_attn_with_kvcache for cached decoding by @danielhanchen in #12112
- Fix Gemma and Gemma2 embeddings scaled twice on transformers 5.4+ by @danielhanchen in #12116
- Keep scan_packages.py from tripping Bitdefender's Python stealer signature by @danielhanchen in #12169
- Studio: show when a prompt was sent while hovering it by @shimmyshimmer in #12170
- Studio: add a Scroll while generating setting (Auto-scroll or Manual) by @shimmyshimmer in #12110
- Studio: make compile knobs reach the render thread on torch 2.12+ by @danielhanchen in #12075
- Studio: stop a hung system node or npm from stalling setup by @oobabooga in #12165
- Studio: price MLX loads in the memory panel and fit an unpinned context to available memory by @Lyxot in #10287
- Gemma2: keep softcapping attention under int32 indexing and fall back to eager if compile fails by @danielhanchen in #12154
- Fix training with accelerate 1.15 on torch without a distributed backend (AMD Windows ROCm) by @danielhanchen in #12162
- Studio: stop runaway tool output from using up memory by @NilayYadav in #11723
- Studio: reset the download progress bar when a retry restarts the file by @NilayYadav in #11593
- Studio: Select all only picks the models the search shows by @NilayYadav in #11485
- Studio: ignore an SSLKEYLOGFILE the process cannot write instead of failing every HTTPS client by @danielhanchen in #12166
- Tests: stop Windows tests tripping Bitdefender and the 16-bit application dialog on real machines by @danielhanchen in #12167
- Studio: Chats library in the Library by @shimmyshimmer in #12122
- Studio: round hover for the Settings close button by @shimmyshimmer in #12172
- unsloth start opencode: size the output limit to the context and add --max-tokens by @shimmyshimmer in #12111
- SAC probe: verify Studio identity before sending a password by @danielhanchen in #12176
- Attention resolver: respect a declared _supports_sdpa = False, and skip flash_attention_2 when a class's compatible flash kernels exclude it (MiMo-V2-Flash) by @danielhanchen in #12147
- Keep Nemotron-H mixer.out_proj unquantized under a caller's BitsAndBytesConfig by @danielhanchen in #12131
- Phi-4-reasoning-vision: give remote multimodal prep an indexable cache view on transformers 5 by @danielhanchen in #12123
- Studio: LTX-2.3 about 4.5x faster per clip (unguided distilled sampling, compile fixes, hosted FP8) by @danielhanchen in #12067
- Let a loaded Kimi K2.5 / K2.7 processor take processor(text=..., images=...) by @danielhanchen in #12126
- Build the native image processor at defaults when a VLM repo has no preprocessor_config.json by @danielhanchen in #12125
- Refuse K-EXAONE 2.0 on a transformers that ignores its config by @danielhanchen in #12128
- Studio: list at most the 12 most recently active projects and sections in Move to by @shimmyshimmer in #12155
- Turn off the MoE aux loss for dense models that carry a router config by @danielhanchen in #12076
- Studio: keep conversation recall working across repeated compactions by @danielhanchen in #12174
- Studio: never ask for approval to run search_conversation by @danielhanchen in #12175
- Add a CI gate for code shapes that heuristic antivirus scanners quarantine by @danielhanchen in #12178
- Dequantize block-FP8 weights with a ragged last block on 16-bit loads (GLM-5.3) by @danielhanchen in #12133
- Rebuild CohereTokenizer from tokenizer.json when transformers v5 changes its ids by @danielhanchen in #12130
- Keep flash attention off towers the Auto classes do not register by @danielhanchen in #12129
- Keep Linear layers an FP8 checkpoint stores in bf16 unconverted by @danielhanchen in #12124
- Load speech-to-text models (Voxtral, Qwen2-Audio) through FastModel by @danielhanchen in #12127
- Narrow Kimi-K3's zero-padded KDA A_log to num_heads so the fla backward runs by @danielhanchen in #12132
- Repair chat templates that always append the generation prompt, also on FastModel loads by @danielhanchen in #12139
- Route GKD distillation through the chunked generalized JSD by @danielhanchen in #12136
- Studio: list HF cache models written without symlinks in the local inventory by @danielhanchen in #12156
- Studio: read public Hub repos without a saved token the Hub rejects by @danielhanchen in #12158
- Studio: list a crashed or cancelled run's saved checkpoints on the Export page by @NilayYadav in #11600
- Studio: pick the right model size when the file names are lowercase by @NilayYadav in #11722
- Refresh WSL shortcut icons through Python instead of an emitted native stub by @danielhanchen in #12184
- Read the gradient checkpointing precondition off transformers' own method by @danielhanchen in #12187
- Studio: Triton-fused VAE norms, caches and attention for every image and video VAE (1.7x to 6.3x decode) by @danielhanchen in #12078
- Studio: fix Decision API validation and TypeSafe SDK metadata by @wasimysaid in #12186
- Studio: grant MXC Tier 3 read access to runtime folders once, not per launch by @danielhanchen in #12121
- Studio: tell a rejected Hugging Face token apart from an unreachable Hub by @danielhanchen in #12159
- Studio: run the isolated Windows Terminal on cmd.exe with stock git when Git Bash cannot start in MXC by @danielhanchen in #12164
- Studio: load a downloaded GGUF from disk when the Hub cannot be read or refuses it by @danielhanchen in #12161
- Join the npm scanner's credential path markers from pieces by @danielhanchen in #12181
- Pass the MXC host-prep script as plain text instead of an encoded command by @danielhanchen in #12182
- Count only the retry loop's own sleeps in the JSON fallback backoff test by @danielhanchen in #12189
- Store the Studio sandbox credential path names in pieces by @danielhanchen in #12188
- Name utf-8 on the SSLKEYLOGFILE writability probe by @danielhanchen in #12190
- Studio: fused int8 MLP kernels and real-arithmetic RoPE for DiT denoisers (FLUX.1 11% less GPU time per step) by @danielhanchen in #12083
- Studio: capability tags in the model picker match the vision pill and get their own colours by @danielhanchen in #12192
- Studio: fix inductor CantSplit on torch 2.12/2.13 and speed up the Qwen-Image-2.1 VAE by @danielhanchen in #12059
- Load block-FP8 checkpoints in 4-bit (NF4) when load_in_4bit=True is passed by @danielhanchen in #12146
- Studio: compile FLUX.1 dynamic, CUDA-graph the SDXL U-Net, decode one-frame Qwen-Image latents in 2D by @danielhanchen in #12060
- Studio: compile VAEs by repeated block, one H3 graph per first render, vectorise the HunyuanVideo-1.5 VAE mask by @danielhanchen in #12061
- Unsloth Studio: stop a Mac browser hiding GPU-only models from a remote CUDA / ROCm / Intel server by @danielhanchen in #8833
- Studio: return no-op instead of 500 for an out-of-range scan folder id by @danielhanchen in #8397
- Do not reinstall llm-compressor when it is already installed by @danielhanchen in #6806
- Fix Studio launcher repair for missing install id by @danielhanchen in #6933
- Load Mistral-format checkpoints (params.json only) through transformers' Mistral4 (Mistral-Large-3) by @danielhanchen in #12144
- Studio: name the MCP server while the tool call is still streaming by @danielhanchen in #9212
- Stop gpt-oss generation at the harmony tool call token by @danielhanchen in #11449
- Studio: vendor laya 0.3.5 and hold its weights in float16 by @danielhanchen in #12202
- Unpack the mirrored uv wheel with python3 -m zipfile instead of an inline one-liner by @danielhanchen in #12194
- Keep xFormers attention causal when the decoder is called without a mask by @danielhanchen in #12199
- GKD: right-align left-padded rows before the student forward by @danielhanchen in #12200
New Contributors- @L4XB made their first contribution in #11803
- @Abhishek-B-R made their first contribution in #11779
- @tweekli made their first contribution in #11781
- @goodmai made their first contribution in #11907
- @breken-ai made their first contribution in #11893
- @MohammadHijjawi97 made their first contribution in #11923
Full Changelog: v0.1.815-beta...v0.1.900-beta |
Performance and Compatibility
Performance is one of Unsloth's main purposes. Its training optimizations are designed to reduce memory requirements and speed up fine-tuning compared with conventional training workflows.
Actual performance depends heavily on the model, quantization, GPU, available VRAM, dataset, batch size, and training configuration. The project supports multi-GPU setups and provides specialized guidance for newer NVIDIA hardware, AMD GPUs, Intel GPUs, and Apple silicon.
Unsloth Studio can run on Windows, Linux, WSL, and macOS. The project also provides native desktop packages for Windows, macOS, and Linux, while the Studio interface can be installed separately and accessed through a local web interface.
macOS users can run models through MLX and GGUF, while supported Apple Silicon systems can also perform training workflows. NVIDIA GPUs provide the broadest support for training workloads, while AMD and Intel support varies by backend and feature.
Because Unsloth works with local models, storage requirements can become significant. Model weights, datasets, checkpoints, caches, and exported models can consume substantially more storage than the application itself.
System Requirements
Unsloth does not have one fixed hardware requirement because different workloads have very different resource requirements.
Supported platforms include:
For the code-based installation, the current documentation uses Python 3.13 with uv for Linux, WSL, and Windows installations.
GPU training requires a compatible backend and sufficient memory for the selected model and training configuration. Larger models generally require more VRAM or system memory, while quantized models can substantially reduce the memory requirement.
Docker is also supported, with official images available for different environments and GPU configurations.
Pros and Cons
Pros
Free and open source
Local model inference
Fine-tuning support
Memory-efficient training optimizations
Supports multiple model types
GGUF support
MLX support
RAG capabilities
MCP support
Tool calling
Code execution
Multi-GPU support
Windows, Linux, WSL, and macOS support
NVIDIA, AMD, Intel, and CPU support
Apple Silicon support
Docker support
Desktop application
Web interface
Python-based workflows
Supports AI coding agents
Cons
Hardware requirements vary significantly by model
Large models require substantial VRAM or system memory
Training workflows can be technically complex
Different hardware backends do not provide identical capabilities
Model files and training datasets can consume considerable storage
Some advanced workflows require command-line or Python knowledge
How to Install
The simplest option is Unsloth Desktop. The project provides native packages for Windows, macOS, and Linux. Linux users can choose DEB or AppImage packages, while macOS and Windows have dedicated installers.
For Unsloth Studio, macOS, Linux, and WSL can use:
curl -fsSL https://unsloth.ai/install.sh | sh
Windows can use:
irm https://unsloth.ai/install.ps1 | iex
After installation, start the Studio interface with:
unsloth studio
The interface runs locally and can be accessed through a web browser.
For developers who prefer the Python package, Unsloth Core can be installed inside a virtual environment. The project currently recommends using uv to create the environment and install Unsloth with automatic PyTorch backend selection.
Docker is another option for users who prefer an isolated environment or need a reproducible setup.
Final Verdict
Unsloth is more than a fine-tuning library. Its current ecosystem combines local model inference, training, model conversion, RAG, tool calling, AI agents, and a graphical Studio interface into a single open-source platform.
Its biggest strength is flexibility. Users can start with the desktop application and local models, then move to Python-based fine-tuning or Docker when they need more control. Support for multiple hardware platforms also makes it useful across a wider range of systems, although the available capabilities vary between backends.
The main limitation is complexity. Unsloth is aimed at users working with local AI models rather than people looking for a simple chatbot. Model size, VRAM, training configuration, and hardware compatibility all have a significant impact on the experience.
Post a Comment/Report Broken Link: